Silicon
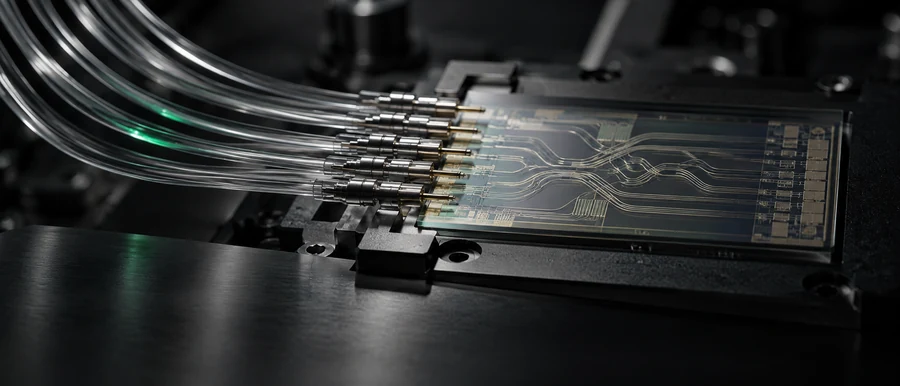
PsiQuantum turns to light to reconnect GPUs
PsiQuantum has unveiled an optical circuit switch derived from its quantum platform. Its value will depend on scaling the hardware and choosing useful connections in software.
GPUs & Silicon
GPUs, HBM memory, NVLink interconnects and microarchitecture: what really sets the performance and cost of AI compute, from the die to the datacenter.
16 articles , page 1 of 2
Silicon
PsiQuantum has unveiled an optical circuit switch derived from its quantum platform. Its value will depend on scaling the hardware and choosing useful connections in software.
Silicon
AMD challenges NVIDIA Vera with EPYC Venice. Agent tool execution puts CPUs in focus, but per-core, server and rack estimates measure different things.
Silicon
Huawei has announced Atlas 960E with up to 4,096 accelerators. Can competition move from the chip to the whole system?
Silicon
A single GPU rack already draws more than 2,000 amps. At 1 MW, today's 54 V distribution would need close to 20,000: here is why NVIDIA and the hyperscalers are moving to 800 V DC, and what remains unsolved.
Silicon
Your model has outgrown one GPU. AMD and NVIDIA offer different ways to make room, but total memory alone will not tell you which system fits your work.
Silicon
Ryzen AI Halo and DGX Spark both offer 128 GB, but performance changes with model and protocol. Vendor claims and independent LLM tests, audited.
Silicon
BlueField-4 and Pensando Salina compute no tokens. They move networking, storage, security and selected KV-cache transfers away from the host CPU. Here is the data path that can free the GPU, or merely move the bottleneck.
Silicon
UALink 2.0 standardizes compute inside the network; NVLink 6 integrates it into its switches. Here is what the mechanism changes, and why Helios and Vera Rubin still cannot be ranked.
Silicon
Assess a 96 GB M3 Ultra for local LLMs: 819 GB/s bandwidth, model weights, context and MLX. Includes the distinction from the current M5 Ultra catalog.
Silicon
An RTX PRO 6000 and three RTX 5090s each add up to 96 GB of GDDR7. For an LLM, that is where the equality ends: one pool, one sharded model and three independent replicas pay different costs.
Silicon
RTX Spark brings up to 128 GB of unified memory and native CUDA to Windows on Arm. As of August 12, CUDA remains a developer preview, TensorRT-RTX is ready, and the LLM serving stack still needs qualification.
Silicon
The MI455X carries 432 GB of HBM4, versus 288 GB on Rubin. AMD still has to prove that UALoE can turn that capacity advantage into rack-scale performance.