Silicon
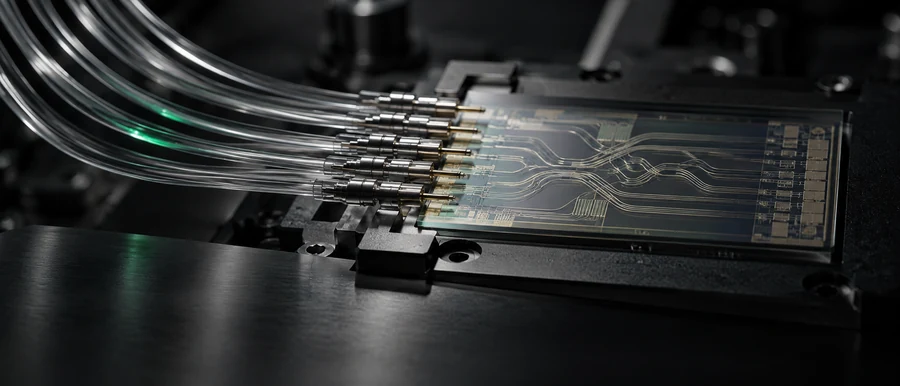
PsiQuantum turns to light to reconnect GPUs
PsiQuantum has unveiled an optical circuit switch derived from its quantum platform. Its value will depend on scaling the hardware and choosing useful connections in software.
Silicon
PsiQuantum has unveiled an optical circuit switch derived from its quantum platform. Its value will depend on scaling the hardware and choosing useful connections in software.
Costs
A Google satellite has returned a Gemma 4 response. Beyond the haiku, Suncatcher tests the power, cooling and communications needed to keep computing in space.
Runtimes
DeepSeek has released its inference engine. The code shows how it speeds up models, and how much infrastructure still separates that engine from a production service.
Costs
Alibaba is bringing chips, models and agent services together. Open weights preserve some choice; adaptations and application state determine what can move elsewhere.
Kernel & Perf
FlashAttention-4 keeps evolving on Blackwell. Between matrix products, softmax and data movement can determine how fast the kernel progresses.
Silicon
AMD challenges NVIDIA Vera with EPYC Venice. Agent tool execution puts CPUs in focus, but per-core, server and rack estimates measure different things.
Costs
Google, NVIDIA and Emerald AI want power flexibility to unlock faster grid connections. Who guarantees the promised reductions?
Costs
NVIDIA promises to keep Hugging Face open. Who will shape the easiest paths to choosing and deploying a model?
Silicon
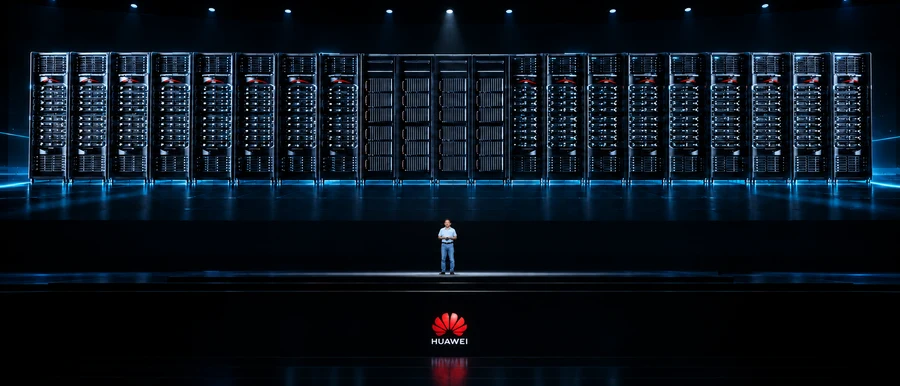
Huawei has announced Atlas 960E with up to 4,096 accelerators. Can competition move from the chip to the whole system?
Runtimes
An inference engine's scheduler does not trade throughput against latency. It trades one latency against another: time to first token versus time between the tokens that follow. Three major engines, three opposite defaults, and nothing tells the operator.
Runtimes
A mixture-of-experts does not remove the cost, it moves it twice: from compute to memory, then from memory to the network. The second shift has a threshold, it can be computed, and it decides your topology.
Costs
A driving model is a function of its data distribution. But the cost of moving it is not where intuition puts it: perception recalibrates for almost nothing, behaviour does not, and validation dominates everything. The entry price for a market is a simulation bill.
Runtimes
GGUF is a file format, while GPTQ and AWQ are quantization algorithms. At 4 bits, each attacks the outlier problem differently. Anatomy of three constructions, from GPTQ's Hessian to GGUF's k-quants, and of what the choice of format decides for you.
Costs
10 gigawatts 'secured years ahead of schedule', 0.3 gigawatt plugged in at Abilene. Behind OpenAI's comeback in AI coding, a compute bet that must be read in three states: the secured, the built, the plugged-in. And a subscription economics that agents cracked open.
Runtimes
On July 8, 2026, OpenAI disavowed SWE-Bench Pro: ~30% broken tasks. It is the third reference instrument declared dead in three generations. Anatomy of a metrology crisis: noise ceiling, contamination, and a harness effect worth a whole model generation.
Costs
On July 8, 2026, OpenAI disavowed the reference benchmark for agentic coding. On the 9th, it merged Codex into the ChatGPT app and launched GPT-5.6. Behind the sequence, a comeback that turns less on intelligence than on prices, subscriptions and the harness.